<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://zhuoran.ai/feed.xml" rel="self" type="application/atom+xml" /><link href="https://zhuoran.ai/" rel="alternate" type="text/html" /><updated>2026-10-11T06:30:05+00:00</updated><id>https://zhuoran.ai/feed.xml</id><title type="html">Shen Zhuoran</title><subtitle>Personal site for Shen Zhuoran, a Founding Scientist at a stealth startup on RSI and AI Scientists.</subtitle><entry><title type="html">Efficient Attention: Attention with Linear Complexities</title><link href="https://zhuoran.ai/ai/2019/12/02/efficient-attention.html" rel="alternate" type="text/html" title="Efficient Attention: Attention with Linear Complexities" /><published>2019-12-02T11:46:40+00:00</published><updated>2019-12-02T11:46:40+00:00</updated><id>https://zhuoran.ai/ai/2019/12/02/efficient-attention</id><content type="html" xml:base="https://zhuoran.ai/ai/2019/12/02/efficient-attention.html"><![CDATA[<p><a href="https://arxiv.org/abs/1812.01243"><em>Efficient Attention: attention with Linear Complexities</em></a> is a work by myself and colleagues at SenseTime. We proposed a simple but effective method to decrease the computational and memory complexities of the attention mechanism from quadratic to linear, without loss of accuracy. This blog post will introduce the method and major results of the paper.</p>

<ul>
  <li><a href="#motivation">Motivation</a>
    <ul>
      <li><a href="#the-attention-mechanism">The Attention Mechanism</a></li>
      <li><a href="#drawback-of-attention">Drawback of Attention</a></li>
    </ul>
  </li>
  <li><a href="#our-method">Our Method</a>
    <ul>
      <li><a href="#a-closer-look-at-the-architecture-diagram">A Closer Look at the Architecture Diagram</a></li>
      <li><a href="#what-about-normalization">What about Normalization?</a></li>
    </ul>
  </li>
  <li><a href="#empirical-validation">Empirical Validation</a>
    <ul>
      <li><a href="#object-detection-and-instance-segmentation">Object Detection and Instance Segmentation</a></li>
      <li><a href="#stereo-depth-estimation-and-image-classification">Stereo Depth Estimation and Image Classification</a>
        <ul>
          <li><a href="#stereo-depth-estimation">Stereo Depth Estimation</a></li>
          <li><a href="#image-classification">Image Classification</a></li>
        </ul>
      </li>
    </ul>
  </li>
  <li><a href="#why-it-matters">Why It Matters?</a></li>
</ul>

<h1 id="motivation">Motivation</h1>
<h2 id="the-attention-mechanism">The Attention Mechanism</h2>

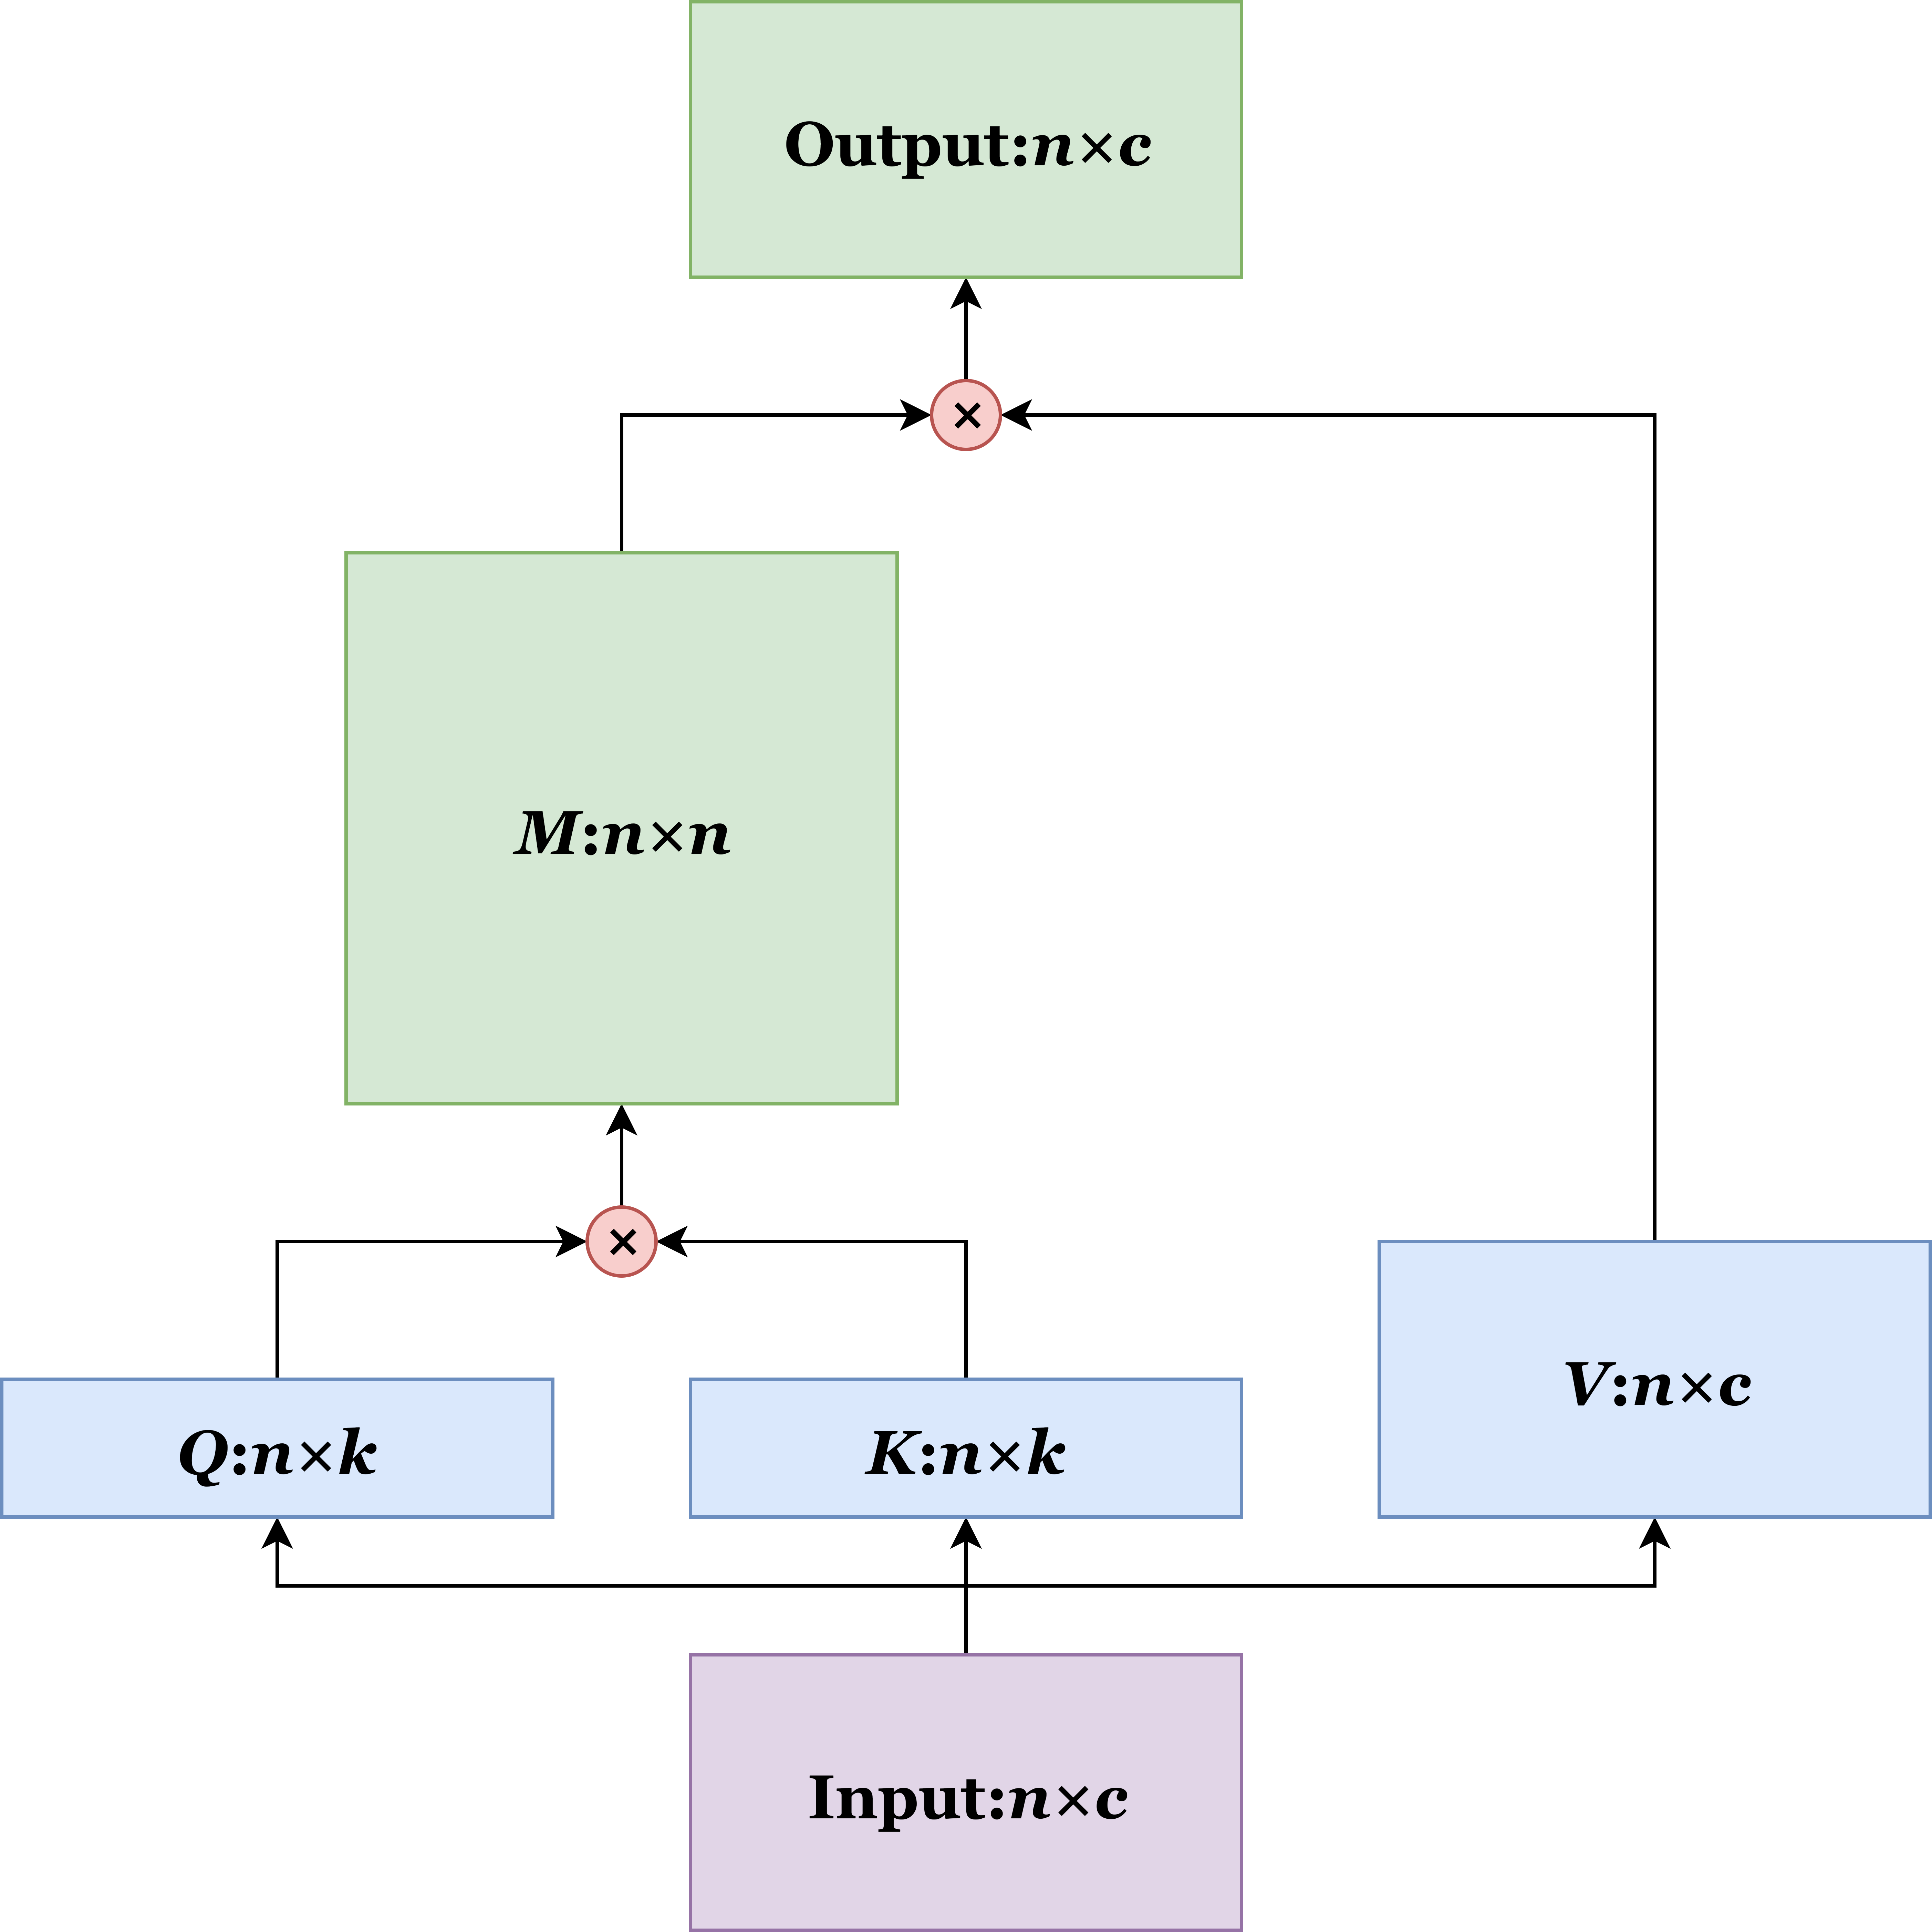
<p>The attention mechanism is a mechanism in neural networks that allows direct connection between each pair of positions in the input. Its core advantage over recurrence and convolution is its ability to modeling long-range dependency. Following is a diagram depicting a typical attention module.</p>

<p><img src="/assets/2019-12-02-efficient-attention/ca.png" alt="Illustration of the network architecture of conventional attention" /></p>

<p>In this diagram, <code class="language-plaintext highlighter-rouge">n</code> represents the number of positions in the input, <code class="language-plaintext highlighter-rouge">k</code> and <code class="language-plaintext highlighter-rouge">c</code> represent the dimensionalities of the keys and the input, <code class="language-plaintext highlighter-rouge">K</code>, <code class="language-plaintext highlighter-rouge">Q</code>, <code class="language-plaintext highlighter-rouge">V</code>, and <code class="language-plaintext highlighter-rouge">M</code> represent the keys, the queries, the values, and the attention masks, respectively. This blog post will assume knowledge of the conventional attention mechanism. For more information on this topic, please refer to this <a href="http://jalammar.github.io/illustrated-transformer/">blog post</a> by Jay Alammar from Udacity.</p>

<h2 id="drawback-of-attention">Drawback of Attention</h2>

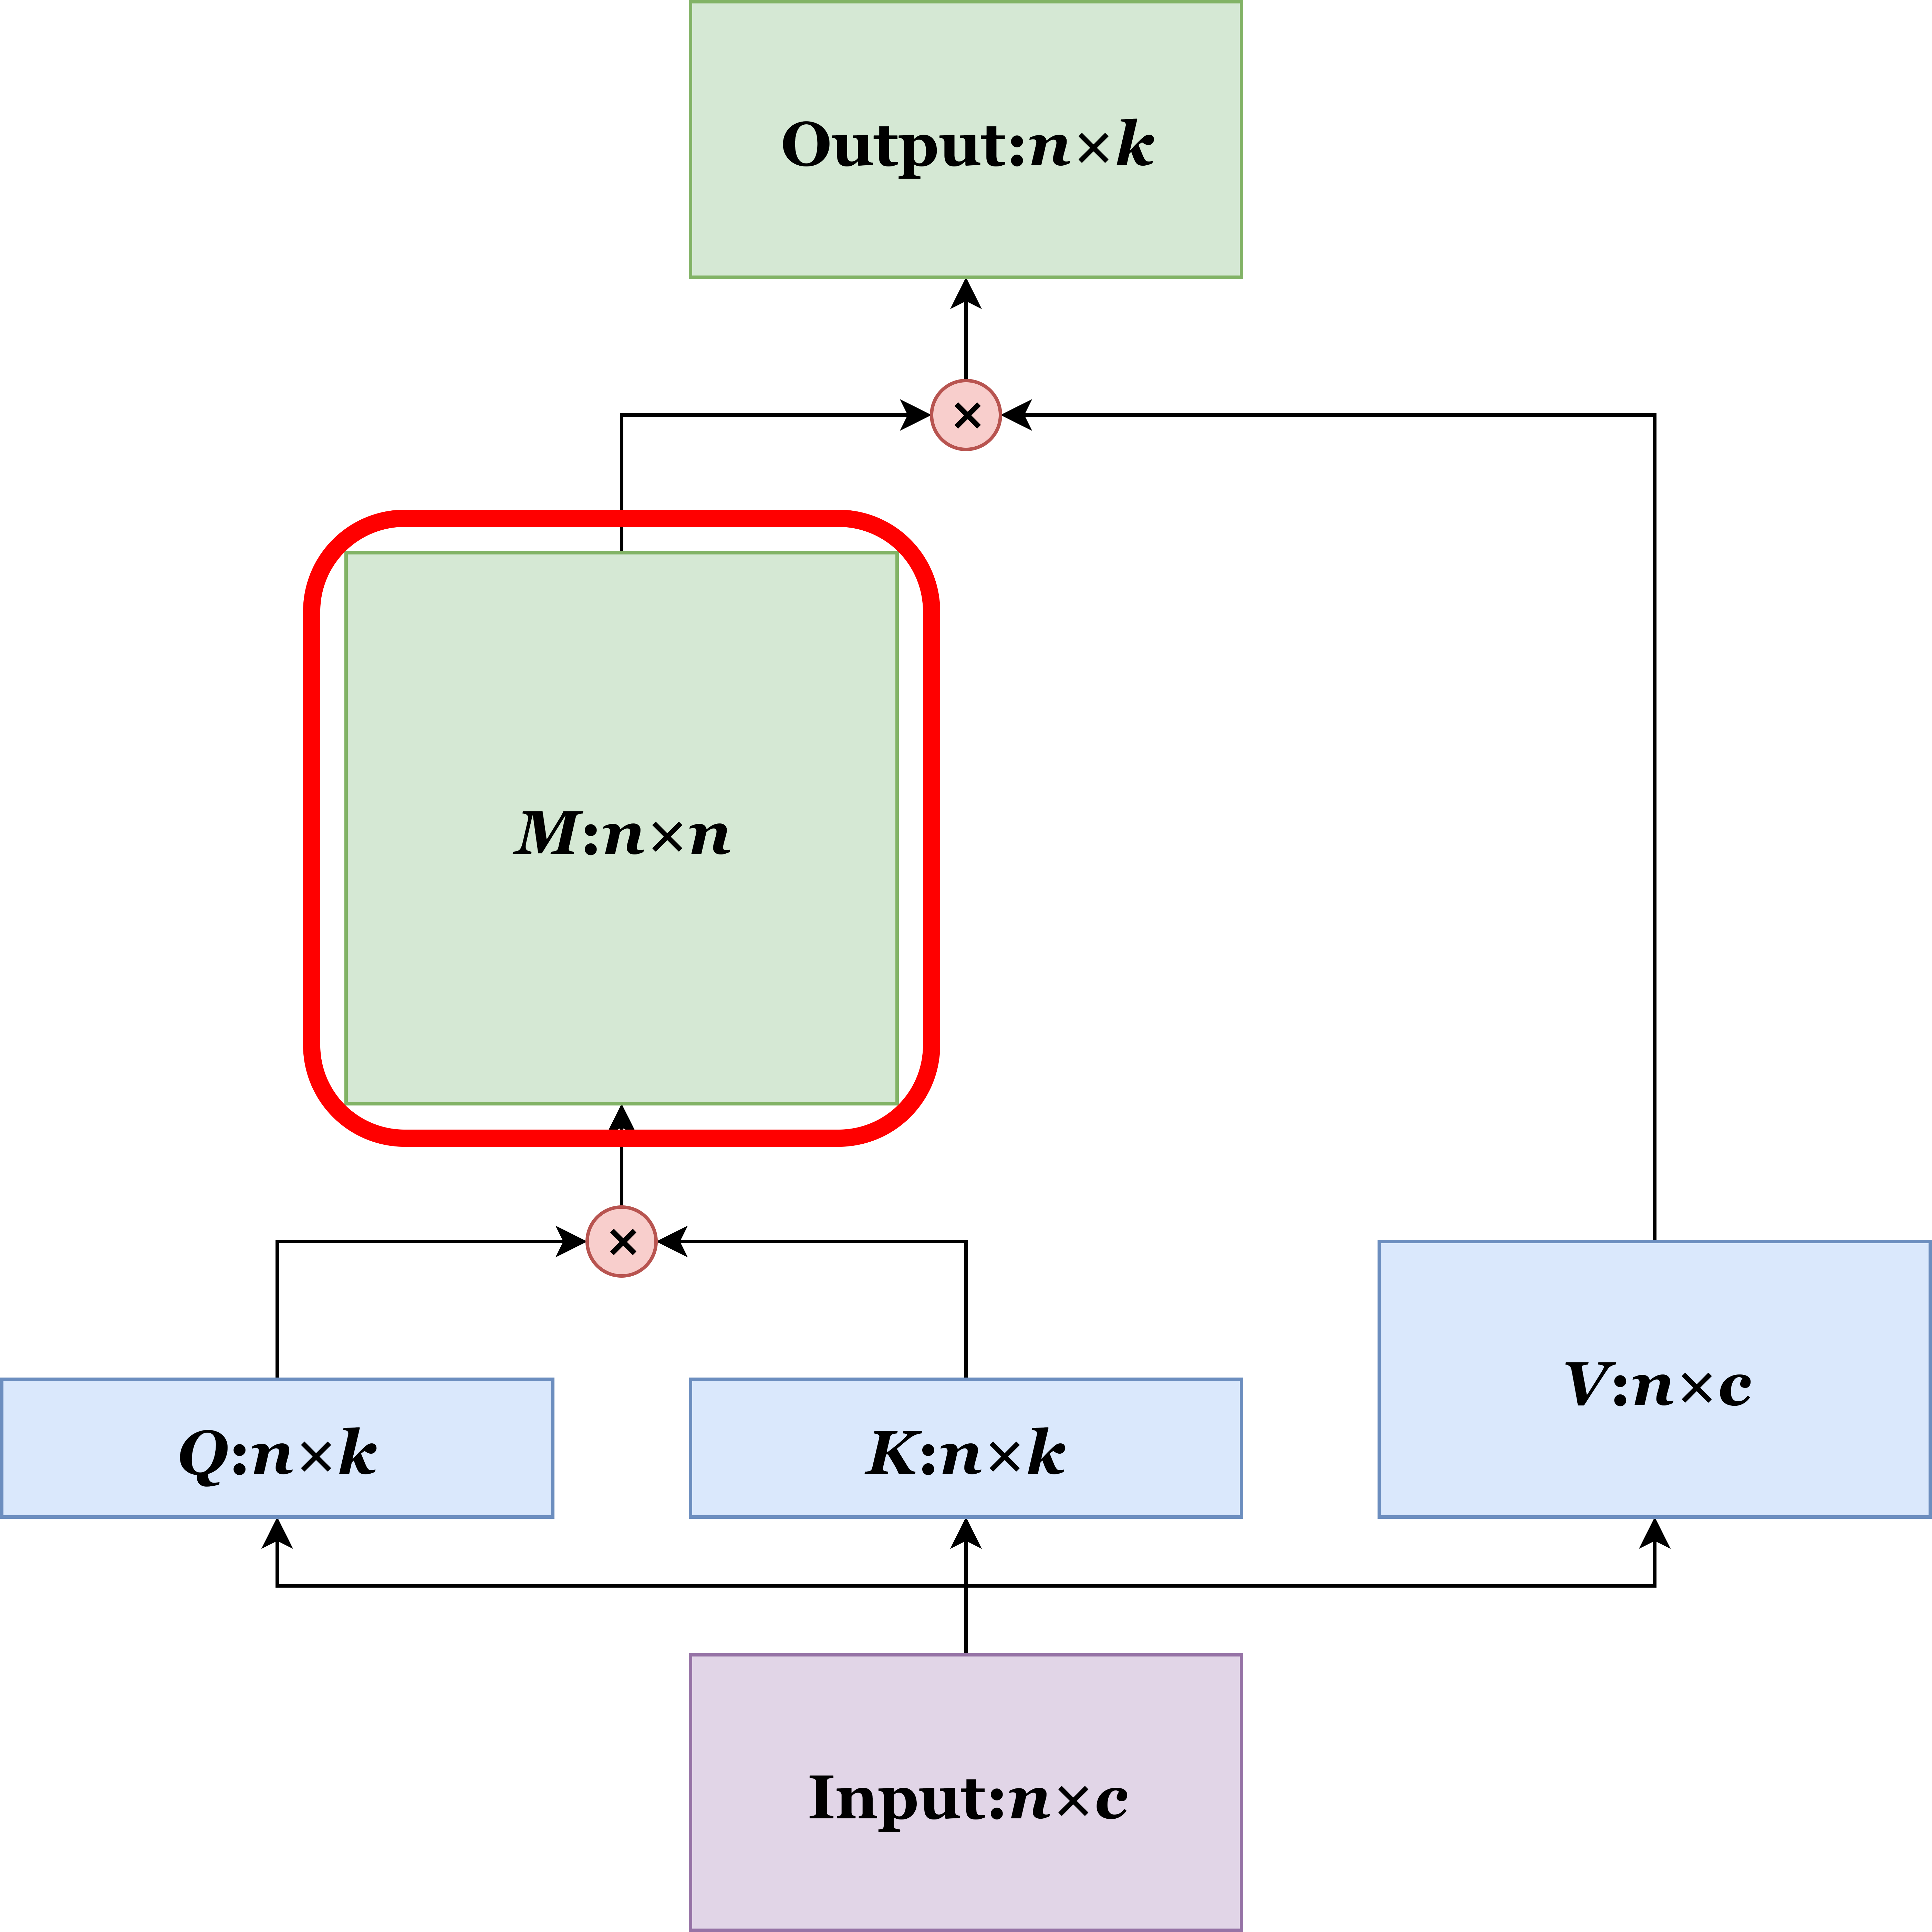
<p>Despite its excellent ability for long-range dependency modeling, attention has a serious drawback. As you can see in the figure above, the intermediate result <code class="language-plaintext highlighter-rouge">M</code>’s shape is <code class="language-plaintext highlighter-rouge">n*n</code>. This means 1) its memory complexity is quadratic; 2) to generate the quadratically many elements, the computational complexity is also quadratic. Consequently, the memory and computational complexities of the entire attention module are quadratic.</p>

<p>This is a critical drawback. As computer scientists, we understand that a quadratic algorithm is much slower than a linear one on large inputs. And the gap grows rapidly as the input gets larger. This effectively forbids the application of attention on large inputs, like high-definition images, long sequences, and large videos. However, these inputs are important in various tasks, like object detection, instance segmentation, stereo vision, and video classification. Therefore, to democratize the attention mechanism to many more fields, it is critical to address its quadratic complexities.</p>

<h1 id="our-method">Our Method</h1>

<h2 id="a-closer-look-at-the-architecture-diagram">A Closer Look at the Architecture Diagram</h2>

<p>To learn how to solve the issue of quadratic complexities, let’s take a closer look at the architecture diagram of the attention module. The most resource-consuming and the only quadratically complex part of the module is the attention masks <code class="language-plaintext highlighter-rouge">M</code> of size <code class="language-plaintext highlighter-rouge">n*n</code>.</p>

<p><img src="/assets/2019-12-02-efficient-attention/ca-bottleneck.png" alt="The attention masks are the most resource-consuming part of an attention module" /></p>

<p>However, if we more closely examine the diagram, we can see that <code class="language-plaintext highlighter-rouge">M</code> is surrounded by two consecutive matrix multiplications, as illustrated below. Now, recall your freshman-year linear algebra course. Matrix multiplication is associative, which means if there are multiple consecutive matrix multiplications, you can choose whatever order to calculate. Therefore, what we can do is to simply swap the order of the two multiplications. Aha! This is the magic.</p>

<p><img src="/assets/2019-12-02-efficient-attention/association.png" alt="Swapping the two multiplications lead to massive saving of resrouce usage" /></p>

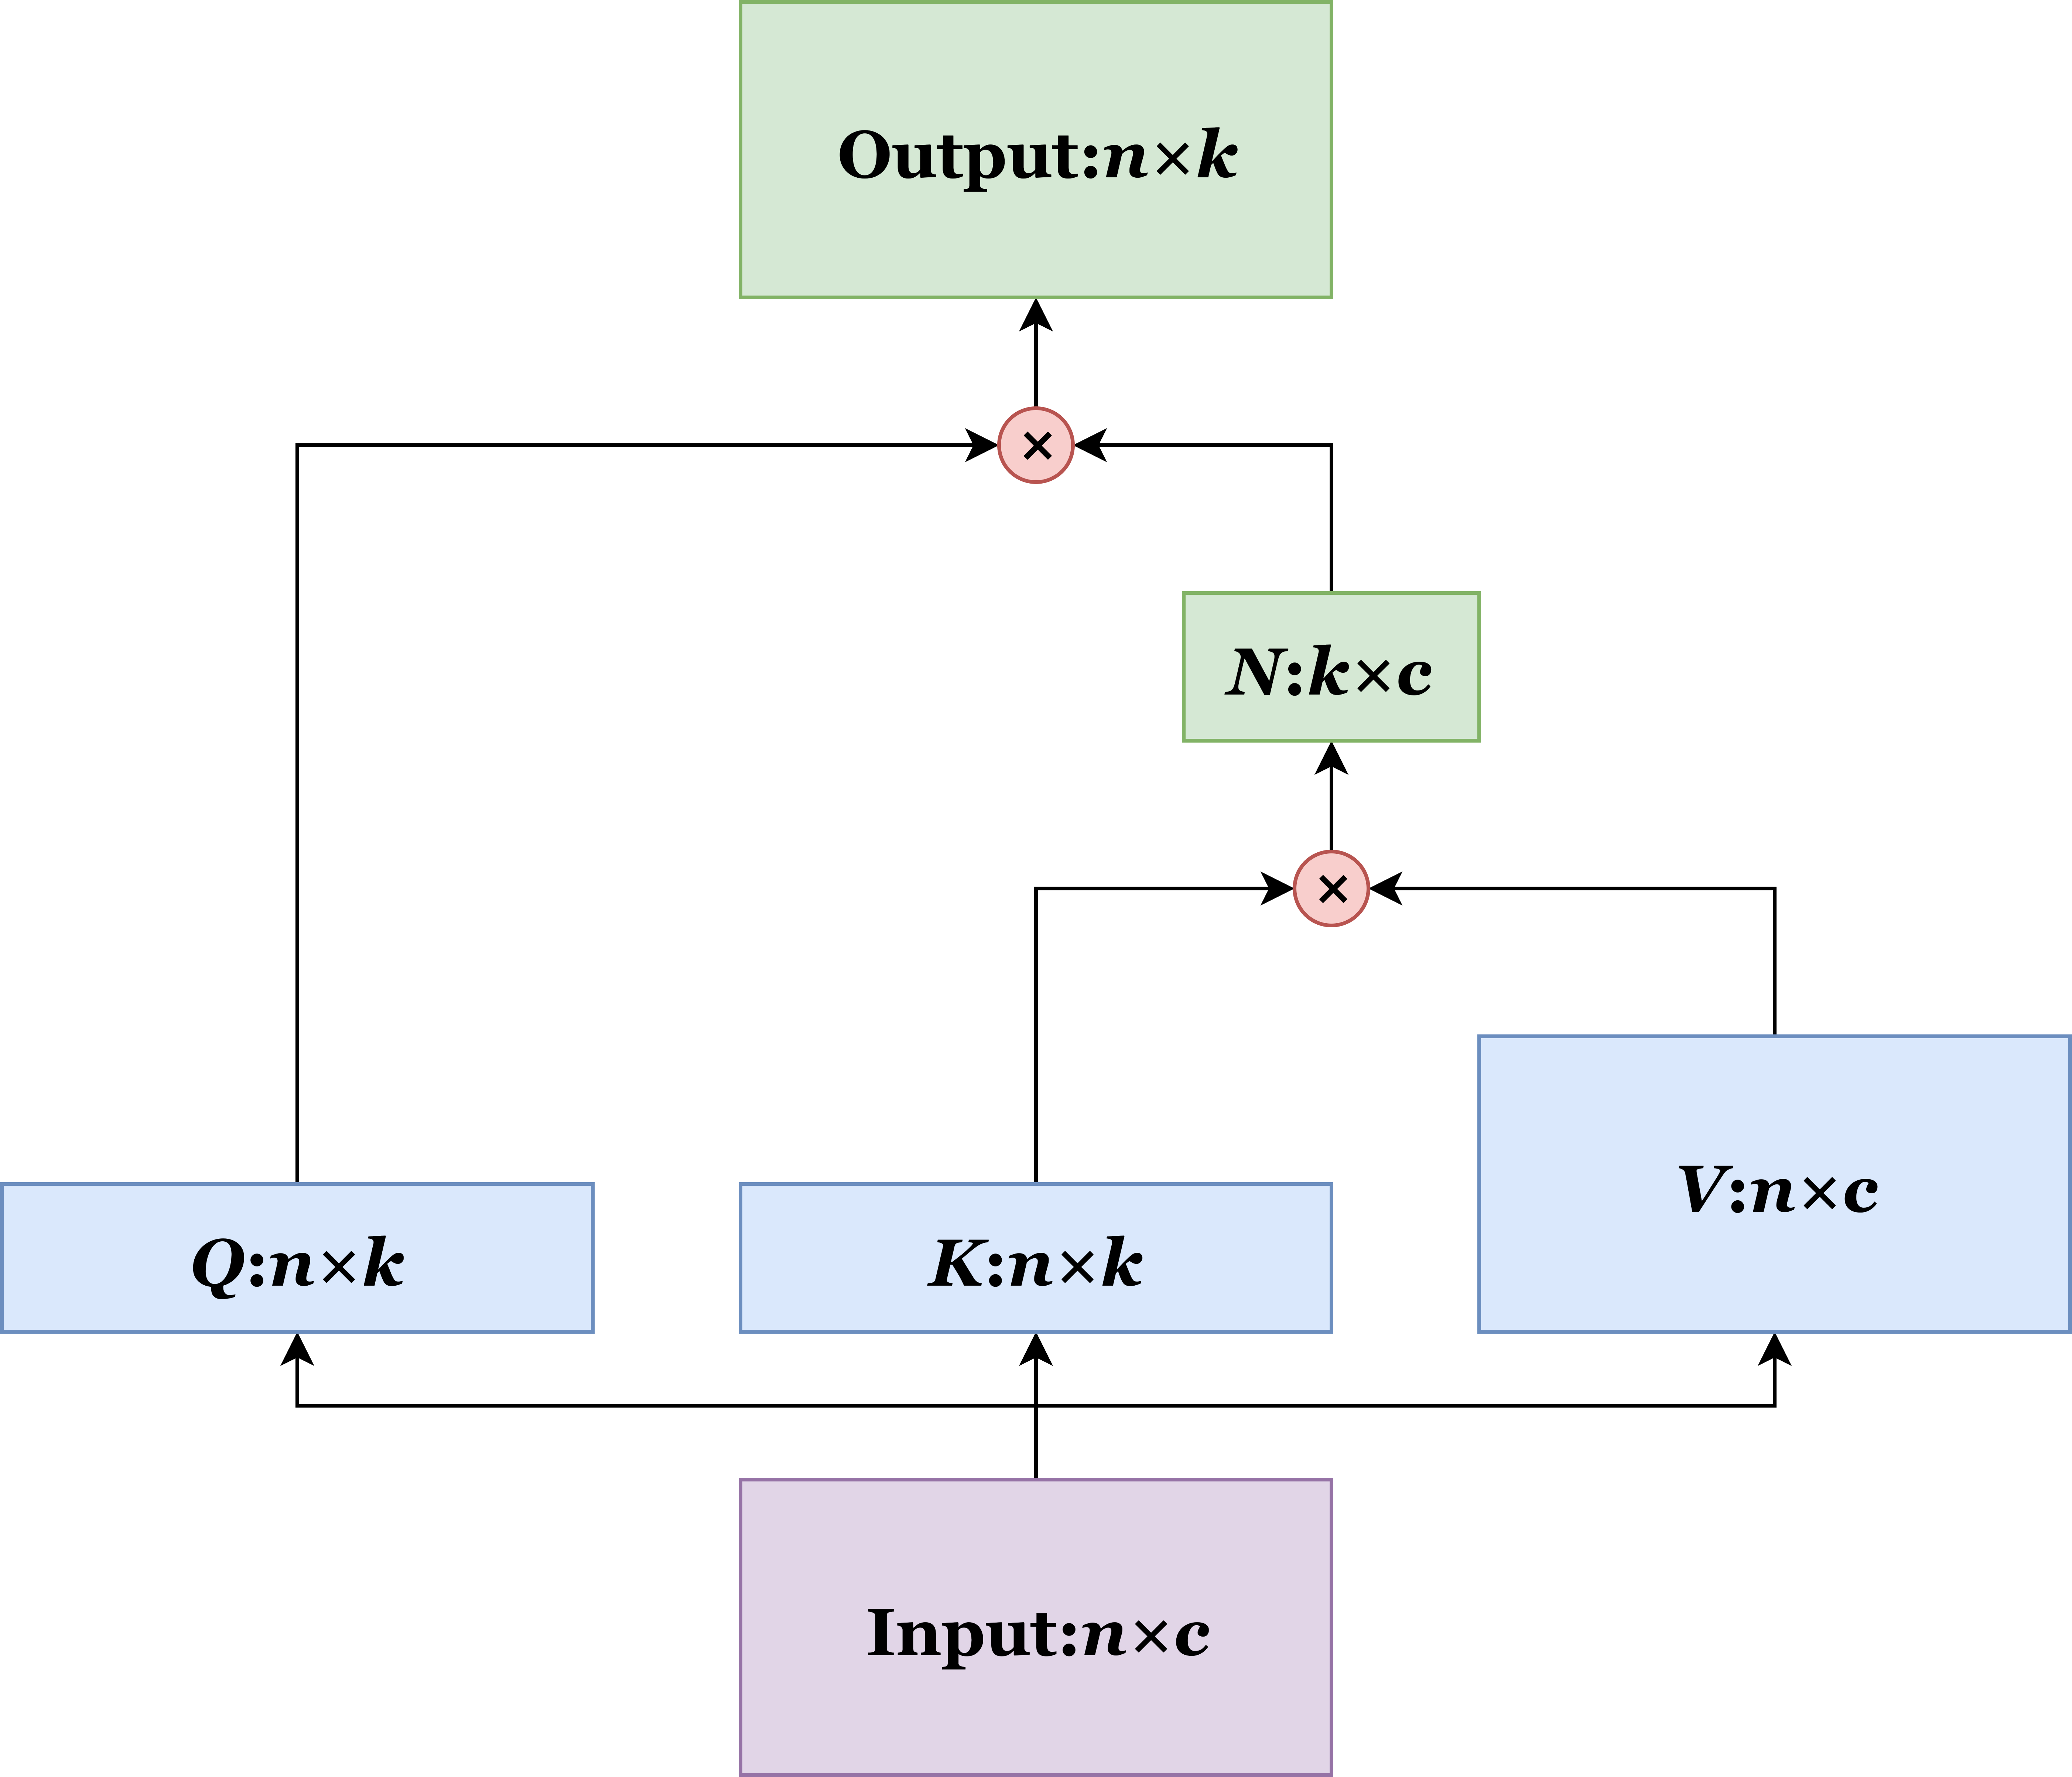
<p>After the swapping, the size of the intermediate result changes from <code class="language-plaintext highlighter-rouge">n*n</code> to <code class="language-plaintext highlighter-rouge">k*c</code>. Since both <code class="language-plaintext highlighter-rouge">k</code> and <code class="language-plaintext highlighter-rouge">c</code> are constants under our control, the resultant memory complexity is <code class="language-plaintext highlighter-rouge">O(1)</code>. After some calculation, you can get the computational complexity, which is <code class="language-plaintext highlighter-rouge">O(n)</code>. This is the <em>efficient attention</em> mechanism.</p>

<p><img src="/assets/2019-12-02-efficient-attention/ea.png" alt="Illustration of the network architecture for efficient attention" /></p>

<h2 id="what-about-normalization">What about Normalization?</h2>

<p>However, the analysis above is only for the vanilla version of attention. In practice, we often apply normalization to the attention masks to stablized training. Will the addition of normalization mess up the analysis? Let’s look into this question with two dominant approaches for attention normalization, scaling normalization and softmax normalization.</p>

<p>For scaling normalization, the question is trivial. Since scaling normalization is merely dividing the attention masks <code class="language-plaintext highlighter-rouge">M</code> by a scalar that depends on <code class="language-plaintext highlighter-rouge">k</code> (<code class="language-plaintext highlighter-rouge">sqrt(k)</code>, to be precise), we can do the exact same thing on <code class="language-plaintext highlighter-rouge">N</code>, and the effect remains unchanged.</p>

<p><img src="/assets/2019-12-02-efficient-attention/association-scaling.png" alt="Illustration of the network architecture for efficient attention" /></p>

<p>The situation is slightly more complicated for softmax normalization. Since softmax is nonlinear, we cannot simply move the operation to <code class="language-plaintext highlighter-rouge">N</code> or anothre matrix. However, we can approximate its effect with two seperate softmax operations on <code class="language-plaintext highlighter-rouge">C</code> and <code class="language-plaintext highlighter-rouge">B</code>, respectively. The softmax on <code class="language-plaintext highlighter-rouge">C</code> is performed along its channel dimension, while the one on <code class="language-plaintext highlighter-rouge">B</code> is along the spatial dimension. After these operations, if we multiply <code class="language-plaintext highlighter-rouge">C</code> and <code class="language-plaintext highlighter-rouge">B</code>, their product will satisfy the same essential property as <code class="language-plaintext highlighter-rouge">M</code> that each row in it sums up to 1. Despite these operations are not exactly equivalent to the original, we have conducted empirical experiments to verify that the approximation doesn’t cause any degradation in performance.</p>

<p><img src="/assets/2019-12-02-efficient-attention/association-softmax.png" alt="Illustration of the network architecture for efficient attention" /></p>

<h1 id="empirical-validation">Empirical Validation</h1>

<p>Okay. So now we have finished presenting the efficient attention module itself. Let’s have a look at how it performs in the real world. We picked 4 tasks to validate its performance: object detection, instance segmentation, image classification, and stereo depth estimation.</p>

<h2 id="object-detection-and-instance-segmentation">Object Detection and Instance Segmentation</h2>

<p>We mainly conducted comparative and ablative studies on these two tasks. For these tasks, we use the standard MS-COCO 2017 dataset.</p>

<table>
  <thead>
    <tr>
      <th>Method</th>
      <th>Box AP</th>
      <th>Mask AP</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>None</td>
      <td>NaN</td>
      <td>NaN</td>
    </tr>
    <tr>
      <td>Scaling</td>
      <td><strong>40.2</strong></td>
      <td>35.9</td>
    </tr>
    <tr>
      <td>Softmax</td>
      <td><strong>40.2</strong></td>
      <td><strong>36.0</strong></td>
    </tr>
  </tbody>
</table>

<p>We first compared the two proposed attention normalization methods. You can see that the two methods perform almost identically. This shows that the effectiveness of the efficient attention module lies in its essential formulation, rather than any specific implementation.</p>

<table>
  <thead>
    <tr>
      <th>Number of modules</th>
      <th>Box AP</th>
      <th>Mask AP</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1</td>
      <td>40.2</td>
      <td>36.0</td>
    </tr>
    <tr>
      <td>5</td>
      <td>40.6</td>
      <td>36.1</td>
    </tr>
    <tr>
      <td>7</td>
      <td><strong>41.2</strong></td>
      <td><strong>36.7</strong></td>
    </tr>
  </tbody>
</table>

<p>After that, we experimented with adding not just one, but multiple efficient attention modules to different parts of the network. (For details on where we inserted the modules and hyperparameter settings, refer to the <a href="https://arxiv.org/abs/1812.01243">paper</a>.) In this table, the trend is that the more you insert, the more (performance) you get. This results shows that the performance advantage provided by the efficient attention module can scale with more of the module included in the network.</p>

<table>
  <thead>
    <tr>
      <th>Backbone</th>
      <th>Baseline AP</th>
      <th>With EA modules</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>ResNet-50</td>
      <td>39.4/35.1</td>
      <td>41.2/36.7</td>
    </tr>
    <tr>
      <td>ResNet-101</td>
      <td>41.3/36.6</td>
      <td>43.1/37.9</td>
    </tr>
    <tr>
      <td>ResNeXt-101</td>
      <td>43.5/38.5</td>
      <td>44.9/39.5</td>
    </tr>
  </tbody>
</table>

<p>Next, we explore the effect of efficient attention on different backbone networks. The table shows that efficient attention is consistently effective on a diversity of backbones. It provides a considerable gain (+1.4 box AP and +1.0 mask AP) even on a highly competitive, ResNeXt-101 baseline.</p>

<table>
  <thead>
    <tr>
      <th>Number of modules</th>
      <th>Efficient attention (box/mask)</th>
      <th>Conventional attention (box/mask)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1</td>
      <td>40.2/36.0</td>
      <td>40.3/35.9</td>
    </tr>
    <tr>
      <td>5</td>
      <td>40.6/36.1</td>
      <td>OOM</td>
    </tr>
    <tr>
      <td>7</td>
      <td><strong>41.2</strong>/<strong>36.7</strong></td>
      <td>OOM</td>
    </tr>
  </tbody>
</table>

<p>Then, we compared the effectiveness of efficient attention against conventional attention. As you can see, when inserting the same number of modules, efficient and conventional attention have very similar performance. When adding more modules, efficient attention’s performance increases steadily. However, the conventional modules quickly experienced out-of-memory errors and wasn’t able to enjoy the benefit brought by incorporating more modules into the network.</p>

<table>
  <thead>
    <tr>
      <th>Method</th>
      <th>Backbone</th>
      <th>AP</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>TDM Faster R-CNN</td>
      <td>Inception-ResNet-v2</td>
      <td>36.8</td>
    </tr>
    <tr>
      <td>Mask R-CNN</td>
      <td>ResNeXt-101</td>
      <td>39.8</td>
    </tr>
    <tr>
      <td>Soft-NMS</td>
      <td>Aligned-Inception-ResNet</td>
      <td>40.9</td>
    </tr>
    <tr>
      <td>Lighthead R-CNN</td>
      <td>ResNet-101</td>
      <td>41.5</td>
    </tr>
    <tr>
      <td>Fitness-NMS</td>
      <td>ResNet-101</td>
      <td>41.8</td>
    </tr>
    <tr>
      <td><strong>EA Mask R-CNN</strong></td>
      <td>ResNet-101</td>
      <td>43.1</td>
    </tr>
    <tr>
      <td><strong>EA Mask R-CNN</strong></td>
      <td>ResNeXt-101</td>
      <td>45.9</td>
    </tr>
  </tbody>
</table>

<p>Finally, we contrasted efficient attention-augmented detectors and instance segmenters against state-of-the-art published methods. EA Mask R-CNN has set  a new state-of-the-art on MS-COCO 2017 object detection and instance segmentation.</p>

<h2 id="stereo-depth-estimation-and-image-classification">Stereo Depth Estimation and Image Classification</h2>

<p>To prove the generalizability of efficient attention, we also tried it on two other important tasks, stereo depth estimation and image classification.</p>

<h3 id="stereo-depth-estimation">Stereo Depth Estimation</h3>

<p>For stereo depth estimation, we used a PSMNet with optimized hyperparameters as the baseline. The dataset used was Scene Flow. We only experimented with adding a single DA module.</p>

<table>
  <thead>
    <tr>
      <th>Model</th>
      <th>EPE</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>iResNet-i2</td>
      <td>1.40</td>
    </tr>
    <tr>
      <td>PSMNet</td>
      <td>1.09</td>
    </tr>
    <tr>
      <td>EdgeStereo</td>
      <td>1.12</td>
    </tr>
    <tr>
      <td>CSPN</td>
      <td>0.78</td>
    </tr>
    <tr>
      <td>EA-PSMNet</td>
      <td><strong>0.48</strong></td>
    </tr>
  </tbody>
</table>

<p>As the table shows, EA-PSMNet has set a record of end-point error (EPE) on the Scene Flow dataset by a large margin.</p>

<h3 id="image-classification">Image Classification</h3>

<p>For image classification, we used ResNet-50 as our baseline and tested on the ImageNet dataset.</p>

<table>
  <thead>
    <tr>
      <th>Number of modules</th>
      <th>Top-1 accuracy (%)</th>
      <th>Improvement</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>0</td>
      <td>76.052</td>
      <td>0.000</td>
    </tr>
    <tr>
      <td>1</td>
      <td>76.932</td>
      <td>0.880</td>
    </tr>
    <tr>
      <td>2</td>
      <td>77.312</td>
      <td>1.260</td>
    </tr>
  </tbody>
</table>

<p>As in the table, the incorporation of a couple of efficient attention modules substantially improves the performance of a ResNet-50.</p>

<h1 id="why-it-matters">Why It Matters?</h1>

<p>Efficient attention dramatically reduces the resource needs of the attention mechanism. It offers three advantages over conventional formulations:</p>

<ol>
  <li>With the same network architecture, efficient attention saves resources.</li>
  <li>Under the same resource budget, efficient attention offers better performance.</li>
  <li>In fields where the application of attention wasn’t possible, efficient attention enables the possibilities.</li>
</ol>

<p>Efficient attention has the potential to democratize attention to many more applications and offers a huge amount of extra freedom in network architecture design.</p>

<p><em>To learn more, refer to the paper on <a href="https://arxiv.org/abs/1812.01243">arXiv</a> or <a href="https://arxiv.org/pdf/1812.01243.pdf">download</a> it.</em></p>]]></content><author><name></name></author><category term="AI" /><summary type="html"><![CDATA[Efficient Attention: attention with Linear Complexities is a work by myself and colleagues at SenseTime. We proposed a simple but effective method to decrease the computational and memory complexities of the attention mechanism from quadratic to linear, without loss of accuracy. This blog post will introduce the method and major results of the paper.]]></summary></entry><entry><title type="html">The Preliminary Eve</title><link href="https://zhuoran.ai/miscellaneous/2019/02/18/preliminary-eve.html" rel="alternate" type="text/html" title="The Preliminary Eve" /><published>2019-02-18T15:39:42+00:00</published><updated>2019-02-18T15:39:42+00:00</updated><id>https://zhuoran.ai/miscellaneous/2019/02/18/preliminary-eve</id><content type="html" xml:base="https://zhuoran.ai/miscellaneous/2019/02/18/preliminary-eve.html"><![CDATA[<p>Today is January 28, 2019, Layue 23, the Year of Earth and Dog, and the Preliminary Eve.</p>

<p>Before saying anything else, I wish you and your family a happy Chinese New Year.</p>

<p>I am not a festival person. However, since I crossed the International Date Line to the other side of the globe, I started wondering when I should celebrate each holiday or birthday. Probably, my obsession for clear-cut decisions and sense of ceremony defeated my tiredness of holidays. Well, the question of when to celebrate is actually quite dull, but every time it gets me for a while. When should I say happy birthday to my friends? When should I post my cherry-picked holiday photos to social media? When should I say happy birthday to myself with my inner speech? It doesn’t feel so right to follow Beijing Time, but it does feel a bit late if I wait for the clock tick in Pacific Time. Luckily, the days in the two time zones do still have several hours of overlap which let me eschew the questions.</p>

<p>I remember in my childhood, the New-Year atmosphere would come with the Preliminary Eve. By then, there would have been snow outside my window. The dirty snow, dry and dead branches, and the gloomy sky were all integral to a New Year in my memory. A dumpling meal would mark the start of the New Year. My parents would be more lenient to me, and I would get the freedom to be excessively childish and playful. Next up would be to purchase New Year’s Goods. I didn’t bother worrying about most of them, but the firework stores did really excite me. My parents would dress me in thick clothes and take me to the temporary tent built on the square before the large shopping mall, where the army green door curtain would be hiding the warmth of the crowd, the special smell of Red Earths (belts of 50,000 firecrackers each), and the festive holiday atmosphere. I wouldn’t have the chance to decide what courses to serve at the Meal of the New Year Eve. But here, it would be my call. Fricative crackers, collisional crackers, Splashy Cylinders, Flashy Spinning Tops, and Little Bees were all my favorites. In the tent in a frozen city, before shelves full of assortments of fireworks, I would have been starting to look forward to the night with thick smoke, deafening explosions, and the smell of fireworks spread in the air.</p>

<p>The memories are so fresh that I can almost still smell the fireworks. Nonetheless, it’s been long since I last had such an experience. Did I turn numb after getting into middle or high school? Did the ban on fireworks dissolve the holiday atmosphere? Or did my parents become too old to have a proper celebration? …</p>

<p>Having moved to the US, the atmosphere of the traditional holidays started to feel increasingly distant. Currently, more and more Chinese are migrating here. I can even hear the familiar language here and there. However, social and cultural environments are still constantly taking us away from the traditions. I didn’t realize the Preliminary Eve was around the corner until Mom reminded me yesterday during our chat on WeChat. I now feel fortunate that the time zone difference saved me from missing the holiday. I’m actually not sure whether the King of Cookers understands time zones and is willing to accept my excuse for forgetting it. Anyways, the North and the South (of China) once again have a disagreement on when we should celebrate the Preliminary Eve, just as they disagree on the name of Yuanxiao/Tangyuan and whether rice dumplings should be sweet or not. The North celebrates it on the 23rd, while the South on the 24th. I’m not the kind of person that would dwell on this issue. However, it does give me an extra excuse to make up for the celebration today.</p>

<p>Right now, I am having fast dumplings in T-shirts and shorts, in the warm and pleasant weather in California. The dumplings are fulfilling the last bits of the sense of ceremony left in my memory. Well, let’s just make this my Preliminary Eve.</p>

<p>Today is January 28, 2019 and Layue 23, the Year of Earth and Dog, Pacific Standard Time and January 29, 2019 and Layue 24, the Year of Earth and Dog, Beijing Time. Both are the Preliminary Eve.</p>

<hr />

<p><em>This post is a translation of an <a href="https://hw311.me/zh/misc/2019/01/28/xiao-nian/">article</a> by Wang Zixu in Chinese.</em></p>]]></content><author><name></name></author><category term="Miscellaneous" /><summary type="html"><![CDATA[Today is January 28, 2019, Layue 23, the Year of Earth and Dog, and the Preliminary Eve.]]></summary></entry><entry><title type="html">A Beginner’s Guide to Getting into Deep Learning</title><link href="https://zhuoran.ai/ai/2019/02/17/into-dl.html" rel="alternate" type="text/html" title="A Beginner’s Guide to Getting into Deep Learning" /><published>2019-02-17T20:37:18+00:00</published><updated>2019-02-17T20:37:18+00:00</updated><id>https://zhuoran.ai/ai/2019/02/17/into-dl</id><content type="html" xml:base="https://zhuoran.ai/ai/2019/02/17/into-dl.html"><![CDATA[<p><strong>TL;DR</strong>: Learn some very basic linear algebra, learn Python, learn deep learning basics, learn a framework (PyTorch recommended), and start making stuff. Two full-time weeks are more than enough. Fast learner might make it in one week or less.</p>

<p>First you need to know some basic linear algebra. A deep understanding of it would provide you with deep insights into how deep learning works, but to start working with it, you only need to know the definitions of and basic operations on vectors, matrices, and tensors (they’re really trivial, don’t be scared by the names). I’m planning to write a blog post to introduce the very basics of linear algebra that you need to know, and will update this answer when it’s finished.</p>

<p>Then you need some programming skills. Python would be preferred, as it’s become the leading language in the field. If you already know programming but need to familiarize yourself with Python, I recommend this interactive course <a href="https://www.codecademy.com/learn/learn-python">Learn Python</a> on codecademy. It took me just like 2–3 hours on a Saturday afternoon to get started with that. You don’t need to pay attention to every detail. Sections like file I/O can be skimmed through or even skipped. You can always refer to the official <a href="https://www.python.org/doc/">Python doc</a> whenever you encounter something new. I don’t really know how long it would take from scratch. My first language was Java, and I learned it before I know what functions and variables are in mathematics and what “while” meant in English, so obviously it took me long to get started with programming. But I guess for someone with better math and English backgrounds and starting with Python, it should much smoother.</p>

<p>After than you would need to learn some deep learning basics, like convolution, pooling, backpropagation, etc. <a href="https://adeshpande3.github.io/adeshpande3.github.io/">Adit Deshpande</a> from UCLA wrote an excellent series of blog posts introducing these ideas. <a href="https://adeshpande3.github.io/adeshpande3.github.io/A-Beginner's-Guide-To-Understanding-Convolutional-Neural-Networks/">Part 1</a> and <a href="https://adeshpande3.github.io/adeshpande3.github.io/A-Beginner's-Guide-To-Understanding-Convolutional-Neural-Networks-Part-2/">Part 2</a> explained the basics of deep learning in very layman, very easily understood language. <a href="https://adeshpande3.github.io/The-9-Deep-Learning-Papers-You-Need-To-Know-About.html">Part 3</a> listed some classical paper that represent major breakthroughs in deep learning since the ImageNet revolution (the start of this wave of deep learning explosion). The paper summaries are superbly written. If you are not going to do academics, then just reading the summaries instead of the original papers will give you a significant boost in your understanding of deep learning.</p>

<p>Finally, you probably want to learn a DL framework so that you can get your hands dirty. I highly recommend <a href="https://pytorch.org/">PyTorch</a>. It’s so intuitive and native to Python that I learned it on a domestic flight. (Sorry you TensorFlow or other framework fans lol.)</p>

<p>Now, you are equipped to pick a task you’re interested in, say some classification or detection task. If you want to start your research, you can already find some latest papers for the task, reproduce them and, then and try to add your own ideas at this stage.</p>]]></content><author><name></name></author><category term="AI" /><summary type="html"><![CDATA[TL;DR: Learn some very basic linear algebra, learn Python, learn deep learning basics, learn a framework (PyTorch recommended), and start making stuff. Two full-time weeks are more than enough. Fast learner might make it in one week or less.]]></summary></entry><entry><title type="html">Tracking the States-of-the-Art for Deep Learning Tasks</title><link href="https://zhuoran.ai/ai/2019/01/08/tracking-sotas.html" rel="alternate" type="text/html" title="Tracking the States-of-the-Art for Deep Learning Tasks" /><published>2019-01-08T13:11:09+00:00</published><updated>2019-01-08T13:11:09+00:00</updated><id>https://zhuoran.ai/ai/2019/01/08/tracking-sotas</id><content type="html" xml:base="https://zhuoran.ai/ai/2019/01/08/tracking-sotas.html"><![CDATA[<p>TL;DR: <a href="https://github.com/cmsflash/deep-learning-sota">Deep Learning SotA</a> is a new, actively maintained, neatly formatted project tracking the states-of-the-art for various tasks of deep learning. Star it if you like it.</p>

<p>Deep learning has been exploding in recent years, with more and more results in a wide range of fields coming out at an unprecedented pace. On the one hand, it shows the prosperity of the discipline. On the other hand, it creates difficulties in tracking the states-of-the-art in various fields.</p>

<p>There are several projects trying to track the SotAs for deep learning tasks. However, each of them has drawbacks. <a href="https://github.com/RedditSota/state-of-the-art-result-for-machine-learning-problems">RedditSota</a> takes a similar approach to this project but: 1) has not been actively maintained recently and 2) does not have a unified format (i.e. each section lists its SotA results in a different and unorganized fashion). <a href="https://www.stateoftheart.ai/">StateOfTheArt.ai</a> is a website attempting to do the same. However, it is heavily crowdsourced without very good management. Therefore, its lists are messy. For example, it has two entries for the ImageNet dataset (<code class="language-plaintext highlighter-rouge">Imagenet</code> and <code class="language-plaintext highlighter-rouge">ImageNet ILSVRC 2012 Validation</code>) and two for Switchboard Hub5’00 (<code class="language-plaintext highlighter-rouge">Switchboard (Hub5)</code> and <code class="language-plaintext highlighter-rouge">Switchboard; Hub5</code>). Its list for speech recognition has a column for Word Error Rate, one for WER, and two for Word Error Rate (clean). It is very confusing and makes it hard to compare metrics among different papers.</p>

<p>Therefore, I created a new project on GitHub, <a href="https://github.com/cmsflash/deep-learning-sota">Deep Learning SotA</a>. It aims to be an actively maintained repository recording and tracking the SotAs in various deep learning tasks. These SotAs are organized into three broad categories, computer vision, NLP, and speech. Within each category, the results are sorted by tasks. Each task records its SotAs in a table. Every entry in every table has the same format, recording the dataset, type (single-model, ensemble, etc.), metric, method, paper, and links to open-source implementation.</p>

<p>I created this project so that everyone can easily see what is the best performance recorded to date on a particular dataset for a certain task and what method achieved that. However, I am only a newbie researcher and certainly cannot track all important progresses in the field. You will highly appreciated if you notice some items are outdated or missing in the repository. You can either raise an <a href="https://github.com/cmsflash/deep-learning-sota/issues/new">issue</a> and start a <a href="https://github.com/cmsflash/deep-learning-sota/compare">pull request</a> for that.</p>]]></content><author><name></name></author><category term="AI" /><summary type="html"><![CDATA[TL;DR: Deep Learning SotA is a new, actively maintained, neatly formatted project tracking the states-of-the-art for various tasks of deep learning. Star it if you like it.]]></summary></entry><entry><title type="html">The Most Comprehensive Article about US Graduate Admissions</title><link href="https://zhuoran.ai/applications/2018/12/21/demystifying-admissions.html" rel="alternate" type="text/html" title="The Most Comprehensive Article about US Graduate Admissions" /><published>2018-12-21T07:10:07+00:00</published><updated>2018-12-21T07:10:07+00:00</updated><id>https://zhuoran.ai/applications/2018/12/21/demystifying-admissions</id><content type="html" xml:base="https://zhuoran.ai/applications/2018/12/21/demystifying-admissions.html"><![CDATA[<p>TL;DR: Link to the article: <a href="https://cs.stanford.edu/people/rkarthik/DAGAP.pdf">Demystifying the American Graduate Admissions Process</a>.</p>

<p>No. I’m not talking this post. I’m an undergrad in Hong Kong applying to US grad schools and am not at all qualified to write the <em>most comprehensive</em> article about US grad admissions.</p>

<p>However, I found an article that might worth such praise. It was produced by <a href="https://cs.stanford.edu/people/rkarthik/index.html">Karthik Raghunathan</a>, a Stanford master’s alumnus who have served in the admissions committee and devoted his time make the article very comprehensive and detailed. The article introduced comprehensively in detail the order of importance of different factors and application materials, the each material affects admissions, and how decisions are made.</p>

<p>Karthic is a computer scienctist with an interest in artificial intelligence (specifically, natural language processing), so his experience should be especially useful for people applying to the currently very hot AI programs.</p>

<p>The article is definitely one of the best materials that helped me understand the admission process and criteria, if not the best. Hope you enjoy and learn a lot from it.</p>]]></content><author><name></name></author><category term="Applications" /><summary type="html"><![CDATA[TL;DR: Link to the article: Demystifying the American Graduate Admissions Process.]]></summary></entry></feed>